An e-commerce site launches a redesign, changes its domain, and three weeks later, half of its new pages still do not appear in Google. The problem is neither the content nor the meta tags: it is the absence of an up-to-date sitemap. Understanding the organization of a website involves this technical file, often relegated to the background, while it directly conditions the ability of search engines to crawl and index each URL.
Sitemap and site migration: the case where everything is at stake
The sitemap is rarely discussed outside the general framework of indexing. Where it becomes truly critical is during a site launch or domain change. The Google Search Central documentation, updated in December 2025, explicitly confirms this: the sitemap is described as a key means for Google to discover the URLs of a newly launched or recently migrated site.
When a site changes its address, the old URLs gradually lose their indexing. Without a sitemap pointing to the new pages, the crawlers have no reliable map to navigate the new structure. This results in orphan pages that Google does not visit, or visits too late.
The logic is simple: the XML sitemap lists the active URLs, their last modification date, and their relative priority. On a stable site with good internal linking, Google eventually finds most pages on its own. On a transitioning site, without a crawl history, the sitemap becomes the only reliable entry point for the crawlers.
To concretely observe how a sitemap structures the navigation of an online news site, one can consult the site carrepresse.biz, which presents its XML sitemap in an accessible manner.
Discovery of the sitemap by Google: robots.txt rather than ping
For a long time, one could notify Google of a new sitemap via a ping mechanism (an HTTP request sent to a specific URL). This is no longer the case. Google has removed this discovery method and refocused the process on two specific channels.
- The declaration in the robots.txt file, via the
Sitemap:directive followed by the full URL of the file. This is the passive channel: Google reads the robots.txt during each crawl and automatically detects the referenced sitemap. - Manual submission or via API through Google Search Console. This is the active channel: we directly indicate to Google where the sitemap is located, and we can track its processing status.
- For Bing, the IndexNow protocol offers a more responsive alternative: each new URL or modification can be reported in real-time, without waiting for the next crawl.
This change has a practical consequence: if your sitemap is not declared in robots.txt and you have never submitted it in the Search Console, Google probably does not know it. We still see sites with a sitemap.xml file automatically generated by their CMS, but never referenced anywhere.
XML Sitemap and site structure: what the file really reveals
The sitemap is not just a simple inventory of URLs. The way it is constructed reflects (or should reflect) the architecture of the site. A well-thought-out sitemap distinguishes main pages from secondary pages, groups content by type, and signals recent updates via the lastmod tag.
On a large site, the technical limit requires splitting the sitemap into several files, coordinated by a sitemap index. This parent file lists each child sitemap. It can be segmented by content category (articles, products, static pages) or by publication date.
This segmentation is not just a technical detail. It allows for quick identification, in the Search Console, of which sections of the site have indexing issues. If the sitemap dedicated to product sheets shows a low coverage rate, we know where to focus the audit. Without this granularity, we are searching for a needle in a haystack.
Lastmod and content freshness: an underutilized signal
The lastmod tag indicates the last modification date of a URL. Many CMS fill it in automatically, sometimes with the current date at each regeneration of the sitemap, making it useless. Google has specified that lastmod is only taken into account if it reflects a real change in content.
On the ground, feedback varies on the concrete impact of lastmod. What is documented is that sitemaps combined with the IndexNow protocol (for Bing and Yandex) allow for updates to be reported in almost real-time. Google, on its side, relies more on the crawl frequency it has already established for the site.
HTML Sitemap for user navigation: complementary but distinct
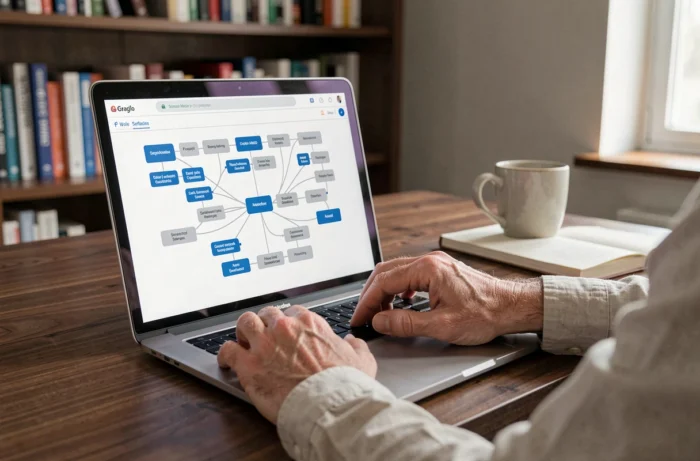
The XML sitemap is aimed at search engines. The HTML sitemap, on the other hand, is a page of the site intended for visitors. It takes the form of a clickable tree structure that lists the main sections and subpages.
Its usefulness depends on the size and complexity of the site. On a blog with twenty articles, it does not add much. On an institutional site with several hundred pages spread across nested sub-sections, the HTML sitemap helps visitors find a page without going through the internal search.
It also plays a role in internal linking: each link in the HTML sitemap passes PageRank to the target page. It is not a major SEO lever in itself, but on a site where some deep pages receive no links from the main navigation, the HTML sitemap partially corrects this flaw.
A common mistake is to confuse the two formats or to believe that an HTML sitemap replaces the XML one. Google’s crawlers do not navigate an HTML sitemap in the same way they read a structured XML file with its standardized tags. The two files serve different needs and coexist without substituting for one another.
A well-declared XML sitemap in robots.txt, segmented by content type and submitted in the Search Console covers the technical part. An HTML sitemap accessible from the footer improves navigation for visitors lost in a complex structure. Neither compensates for a failing internal linking strategy, but both combined give crawlers and users a clear reading of the site’s organization.